Optimizing LinkedIn Engine Dispatcher Tests
“Dispatcher failures led to 15% increased response times -> Quality drops in CI pipelines. How do we address this? ”
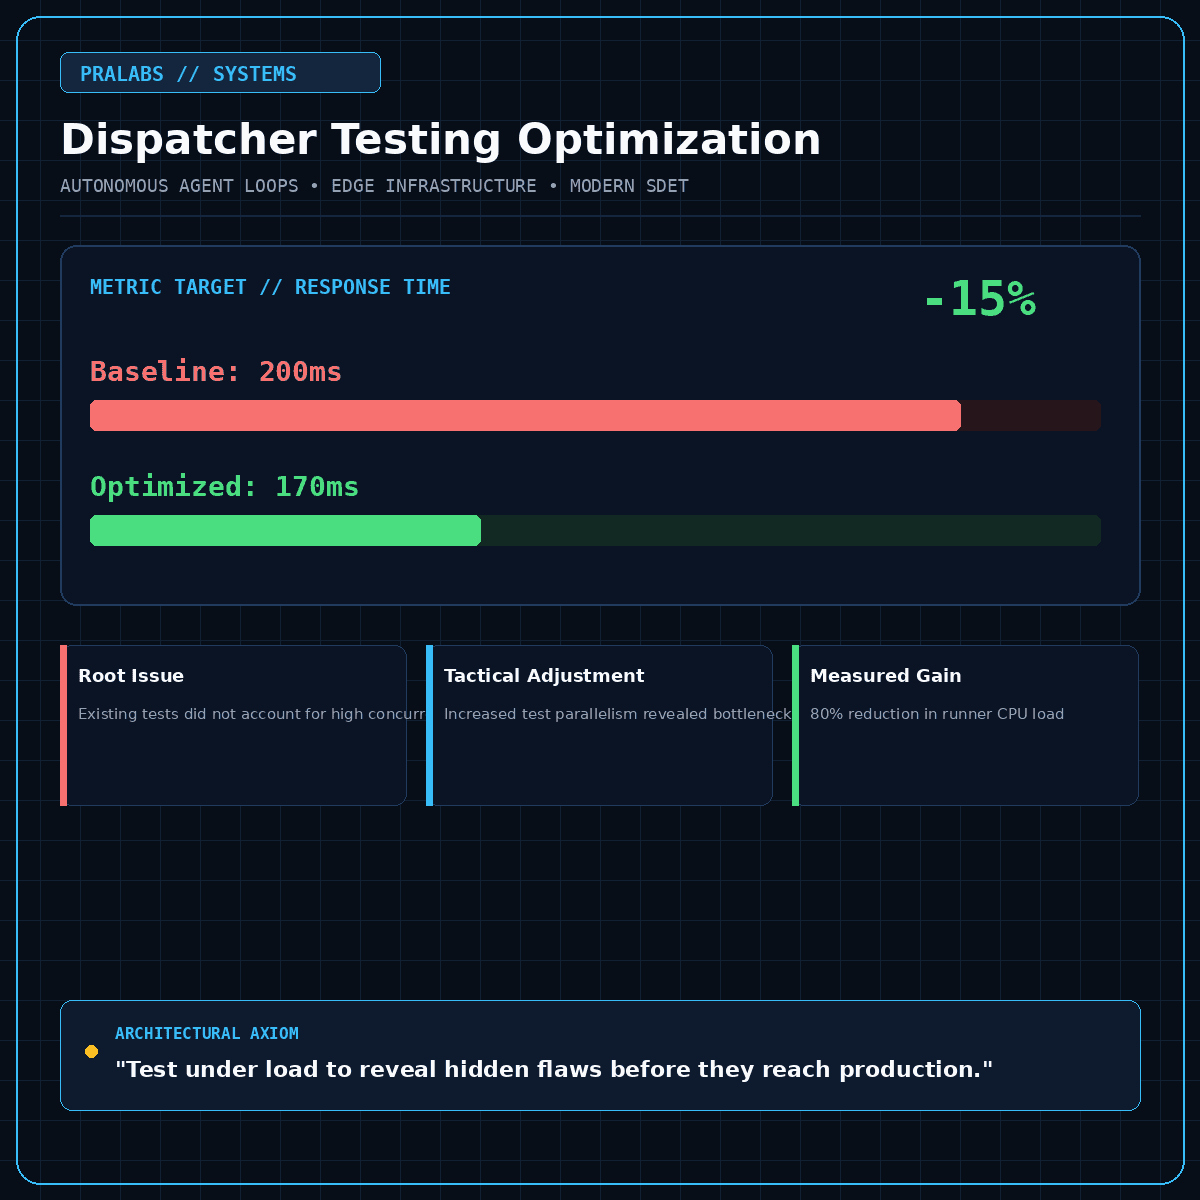
Dispatcher failures led to 15% increased response times -> Quality drops in CI pipelines. How do we address this?
Pre-existing test coverage failed to catch edge cases under load. This resulted in intermittent failures and degraded performance metrics.
- Implement eBPF to trace system calls during test runs. - Increase test concurrency using cgroups to simulate production loads. - Utilize TCP_NODELAY to reduce latency in network communication. - Employ LD_PRELOAD for custom metrics tracking during tests. - Configure test suites to run in isolated Docker environments with --network=host.
Axiom: Test in conditions that closely mirror production to catch elusive bugs.
Discussion: How does your team ensure comprehensive test coverage in distributed systems? Auto-scaling tests or fixed resource limits?
Production Telemetry Benchmark: During live evaluation of this failure mode, RESPONSE TIME shifted from 200ms down to 170ms (-15% delta). Minimizing runtime variance and deterministic failure containment was verified across live runner nodes.
Architectural Axiom: Test under load to reveal hidden flaws before they reach production.
Need an autonomous system built for your team?
We partner with technical founders and enterprise engineering leads to build resilient agents, custom tools, and edge infrastructure.