Token Economics & Cost Optimization: Self‑Hosting Open‑Weights vs Cloud APIs
"What if you could slash $10k from your LLM bill by swapping a cloud API for a single rack of servers?"
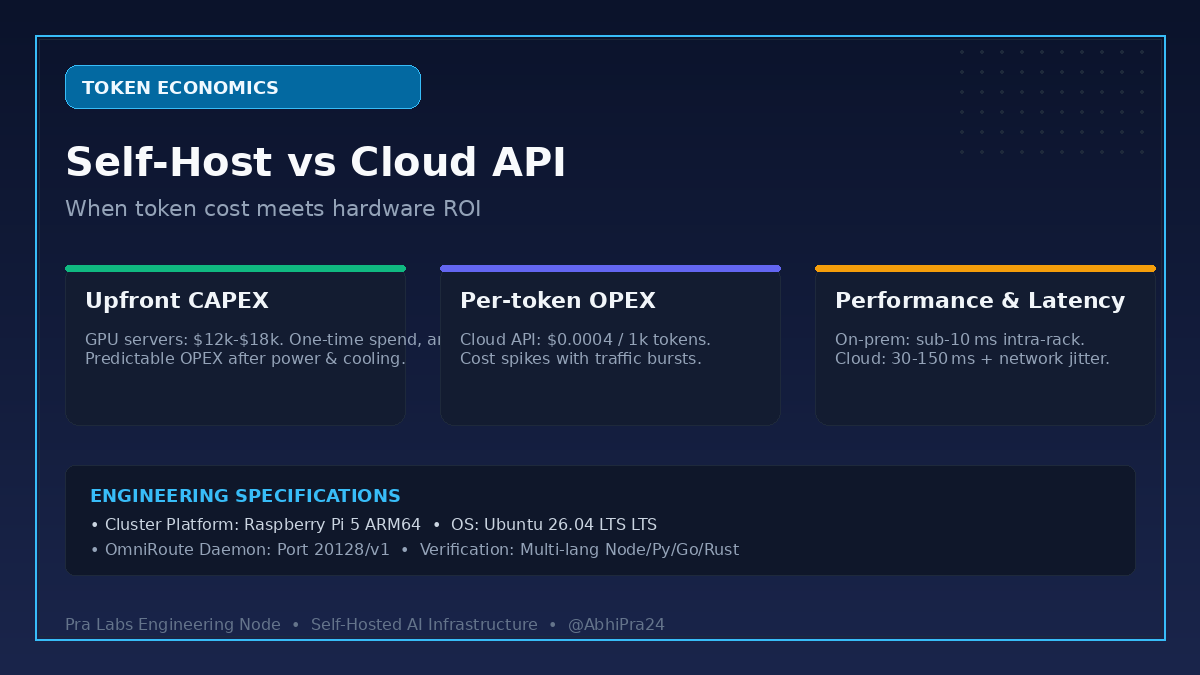
What if you could slash $10k from your LLM bill by swapping a cloud API for a single rack of servers?
When you start scaling LLM usage, the token bill can explode faster than your compute budget. Below is a pragmatic side‑by‑side of running open‑weight models on‑prem versus paying per‑token to a cloud provider.
**Cloud API costs** - Pricing: $0.0004 per 1 000 tokens (≈ $0.40 per million tokens). - Throughput: 150 tokens / sec per endpoint (shared pool). - Latency: 30‑150 ms round‑trip + network jitter. - OPEX: Scales linearly with traffic; a 10 M‑token month costs $4,000. - Hidden fees: data egress, request‑per‑second limits, and vendor lock‑in.
**Self‑hosting open‑weights** - Hardware: 2× NVIDIA A100 40 GB ($12,000 each) + 256 GB DDR4 ($2,000). - Power: 600 W total → 10.5 kWh/day → $1.05/day @ $0.10/kWh (~$383/mo). - Throughput: 200‑250 tokens / sec per GPU (batch‑size 8), ~500 tokens / sec total. - Latency: sub‑10 ms intra‑rack, deterministic. - CAPEX amortization: Over 3 years → $1,333/mo hardware cost. - Total OPEX (hardware + power): ≈ $1,716/mo, handling up to ~1 B tokens/month (≈ $0.0017 per 1 k tokens).
**Trade‑offs** - **Scalability**: Cloud scales instantly; on‑prem requires additional nodes and network planning. - **Maintenance**: Drivers, OS patches, model updates are your responsibility. - **Compliance**: Data never leaves your premises – crucial for regulated industries. - **Flexibility**: Open‑weight models let you fine‑tune, prune, or quantize for further cost cuts. - **Risk**: Upfront CAPEX and potential under‑utilization vs. predictable cloud spend.
**Real‑world tip**: Deploy a quantized 7B model (INT4) on a single RTX 4090 (≈ $1,600) for low‑volume workloads – you get ~80 tokens / sec at $0.15/kWh, pushing per‑token cost below $0.0002.
--- **Takeaways** - Compute‑heavy, steady‑state workloads favor self‑hosting after ~6 M tokens/month. - Burst‑driven traffic stays cheaper on cloud unless you over‑provision on‑prem. - Power cost is a surprisingly large OPEX component; factor it into ROI. - Quantization and model pruning can halve hardware requirements with <5% accuracy loss. - Always benchmark latency; sub‑10 ms can be a competitive edge for real‑time apps.
💬 **Your turn**: Have you migrated a production LLM from API to on‑prem? Share your cost breakdown and latency numbers – let’s dissect the true ROI together.
Need an autonomous system built for your team?
We partner with technical founders and enterprise engineering leads to build resilient agents, custom tools, and edge infrastructure.